


 PDF Version Demo


Online test engine bring you new experience
Besides Pdf version and test engine version, online test engine is the service you can enjoy only from Dumps4PDF. Online version is same as test engine version, which means you can feel the atmosphere of formal test. The difference is that online version allows you practice Associate-Developer-Apache-Spark-3.5 latest dumps pdf in any electronic equipment. You can set limit-time when you do the real Associate-Developer-Apache-Spark-3.5 dumps pdf so that you can master your time when you are in the real test. The online version can point out your mistakes and remind you to practice mistakes everyday, so you can know your shortcoming and strength from the practice of Associate-Developer-Apache-Spark-3.5 exam dumps. What's more, online version allows you to practice the Associate-Developer-Apache-Spark-3.5 test dump anywhere and anytime as long as you open it by internet. When you are waiting or taking a bus, you can make most of your spare time to practice or remember the Associate-Developer-Apache-Spark-3.5 - Databricks Certified Associate Developer for Apache Spark 3.5 - Python latest dumps pdf. Most customers prefer to use it.
Everyone who has aspiration about career will realize their dream by any means, someone improve themselves by getting certificate, someone tend to make friends with all walks of life and build social network. For most IT workers, passing the Associate-Developer-Apache-Spark-3.5 (Databricks Certified Associate Developer for Apache Spark 3.5 - Python) will be a good decision for their career and future. The cost of test is high and the difficulty of Associate-Developer-Apache-Spark-3.5 exam dumps need much time to practice. That is the matter why many people fear to attend the test. To remove people's worries, Dumps4PDF will ensure you pass the Associate-Developer-Apache-Spark-3.5 with less time. You just need to practice the Associate-Developer-Apache-Spark-3.5 latest dumps pdf with your spare time and remember the main points of Associate-Developer-Apache-Spark-3.5 test dump; it is not a big thing to pass the test.
You may wonder how we can assure you the high rate with our Associate-Developer-Apache-Spark-3.5 exam dumps. According to the date shown, real Databricks Associate-Developer-Apache-Spark-3.5 dumps pdf has help more than 100000+ candidates to pass the exam. The pass rate is up to 98%. Our customers comment that the Associate-Developer-Apache-Spark-3.5 latest dumps pdf has nearly 75% similarity to the real questions. Most questions in our Databricks Associate-Developer-Apache-Spark-3.5 dumps valid will appear in the real test because real Associate-Developer-Apache-Spark-3.5 dumps pdf is created based on the formal test. If you practice the Associate-Developer-Apache-Spark-3.5 vce pdf and remember the key points of real Associate-Developer-Apache-Spark-3.5 dumps pdf, the rate of you pass will reach to 85%. So you need to pay great attention to Associate-Developer-Apache-Spark-3.5 exam dumps carefully.

The principle of Dumps4PDF
First, you can download the trial of Associate-Developer-Apache-Spark-3.5 dumps free before you buy so that you can know our dumps well.
Second, you will be allowed to free update the Associate-Developer-Apache-Spark-3.5 exam dumps one-year after you purchased. And we will offer different discount to customer in different time.
Three, we use the most trusted international Credit Card payment; it is secure payment and protects the interests of buyers.
Fourth, we adhere to the principle of No Help, Full Refund. If you failed the exam with our Databricks Associate-Developer-Apache-Spark-3.5 dumps valid, we will refund you after confirm your transcripts. Or you can free change to other dump if you want.
Fifth, we offer 24/7 customer assisting to support you, please feel free to contact us if you have any problems.
After purchase, Instant Download: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Using Spark SQL | 20% | - Spark SQL Operations
|
| Developing Apache Spark DataFrame API Applications | 30% | - DataFrame Operations
|
| Troubleshooting and Tuning | 10% | - Performance Optimization
|
| Apache Spark Architecture and Components | 20% | - Spark Architecture
|
| Using Pandas API on Spark | 5% | - Pandas API
|
| Using Spark Connect to Deploy Applications | 5% | - Spark Connect
|
| Structured Streaming | 10% | - Streaming Applications
|
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
Given a CSV file with the content: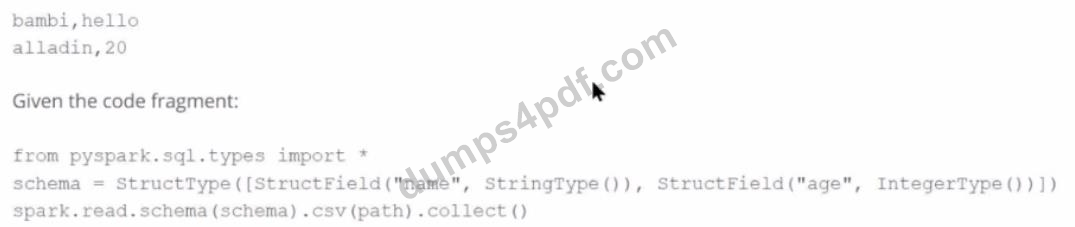
And the following code:
from pyspark.sql.types import *
schema = StructType([
StructField("name", StringType()),
StructField("age", IntegerType())
])
spark.read.schema(schema).csv(path).collect()
What is the resulting output?
- A. [Row(name='alladin', age=20)]
- B. [Row(name='bambi'), Row(name='alladin', age=20)]
- C. The code throws an error due to a schema mismatch.
- D. [Row(name='bambi', age=None), Row(name='alladin', age=20)]
Correct Answer: D 🗳️
Explanation: Only visible for Dumps4PDF members. You can sign-up / login (it's free).
A data engineer is working on the DataFrame: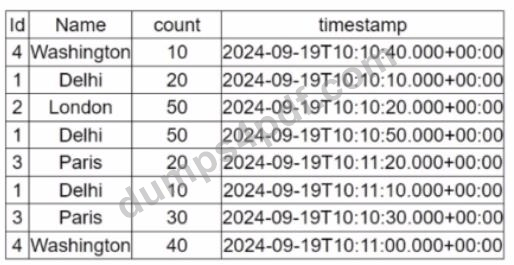
(Referring to the table image: it has columns Id, Name, count, and timestamp.) Which code fragment should the engineer use to extract the unique values in the Name column into an alphabetically ordered list?
- A. df.select("Name").distinct().orderBy(df["Name"].desc())
- B. df.select("Name").distinct().orderBy(df["Name"])
- C. df.select("Name").distinct()
- D. df.select("Name").orderBy(df["Name"].asc())
Correct Answer: B 🗳️
Explanation: Only visible for Dumps4PDF members. You can sign-up / login (it's free).
2 of 55. Which command overwrites an existing JSON file when writing a DataFrame?
- A. df.write.option("overwrite").json("path/to/file")
- B. df.write.mode("append").json("path/to/file")
- C. df.write.mode("overwrite").json("path/to/file")
- D. df.write.json("path/to/file")
Correct Answer: C 🗳️
Explanation: Only visible for Dumps4PDF members. You can sign-up / login (it's free).
43 of 55.
An organization has been running a Spark application in production and is considering disabling the Spark History Server to reduce resource usage.
What will be the impact of disabling the Spark History Server in production?
- A. Improved job execution speed due to reduced logging overhead
- B. Prevention of driver log accumulation during long-running jobs
- C. Loss of access to past job logs and reduced debugging capability for completed jobs
- D. Enhanced executor performance due to reduced log size
Correct Answer: C 🗳️
Explanation: Only visible for Dumps4PDF members. You can sign-up / login (it's free).
A Spark application developer wants to identify which operations cause shuffling, leading to a new stage in the Spark execution plan.
Which operation results in a shuffle and a new stage?
- A. DataFrame.withColumn()
- B. DataFrame.filter()
- C. DataFrame.select()
- D. DataFrame.groupBy().agg()
Correct Answer: D 🗳️
Explanation: Only visible for Dumps4PDF members. You can sign-up / login (it's free).


 Jean

 Sid

 Leonard

 Clara
 Wade
 Lyndon
 Shirley
 Dunn
 Yale
 Merlin
 Setlla
 Mona
 Charles
 Harold
 Beau
 Randolph
 Edwina
 Christine
 Elva
 Stan


